Evaluating Data Leakage in Protein Binding Affinity Prediction
Python
Deep Learning
Convolutional Neural Networks
Self-Attention
Keras
ESM2
Protein Language Models
Data Leakage
Author
Jay Chung
Published
February 25, 2026
Research Impact
Data leakage is a critical issue in machine learning, especially in the context of protein-protein interaction (PPI) prediction. Data leakage occurs when information from the training data is inadvertently used in the testing phase, allowing the model to “remember” specific examples rather than learning generalizable patterns. To address this issue, this post compares two data splitting strategies, regular C3 split and strict C3 split, to evaluate the extent of data leakage when using pre-trained protein large language models (pLLMs) to predict peptide-MHC2 binding. The findings showed that while the neural network model generalized well on predicting binding peptides of seen MHC2 alleles, it struggled to generalize to unseen MHC2 alleles. This highlights the importance of using strict data splitting strategies to ensure that models are evaluated on truly unseen data, which is crucial for developing robust and generalizable models in protein binding affinity prediction.
Introduction
I’ve recently come across this paper about data leakage in PPI prediction models using pLLMs, and it got me thinking about how data leakage might affect other types of protein interaction predictions, such as peptide-MHC2 binding. In this project, I decided to explore this issue by comparing two different data splitting strategies: a regular C3 split and a strict C3 split. The regular C3 split allows for some overlap between the training and testing sets, while the strict C3 split ensures that there is no overlap at all. By evaluating the performance of a neural network model trained on embeddings extracted from a pre-trained pLLM (ESM2) under these two splitting strategies, I aimed to understand the extent of data leakage and its impact on model generalization in the context of peptide-MHC2 binding prediction.
Key Steps
Splitting Strategies: Peptide or MHC sequences were first clustered independently using two different approaches. In both cases, the goal was to ensure that similar protein sequences were not present in both the training and testing sets. Peptides were clustered based on a 3-gram sequence similarity approach, while MHC pseudo-sequences were clustered based on their BLOSUM62 amino acid similarity. After that, the cluster classes were split into training and testing sets using two different strategies largely based on the C3 approach:
Regular C3 split: This split ensures that the test set contains pairs \((Peptide_{new}, MHC_{any})\) and \((Peptide_{any}, MHC_{new})\). This is a less strict C3 split, as it allows for some overlap in the individual components (peptides and MHCs) between the training and testing sets, but not in the interactions.
Strict C3 split: This split ensures that for every pair \((Peptide, MHC)\) in the test set, both \(Peptide\) and \(MHC\) classes are entirely absent from the training set. This is the “Double-Cold” strategy, which is more stringent and ensures that the model is evaluated on completely unseen peptides and MHCs, thus providing a more accurate assessment of the model’s generalization capabilities. A down side of this split is that it results in a smaller training and testing set. To ensure a fair comparison between the two splits, the sample number from the “regular C3 split” was downsampled to match the sample number from the “strict C3 split”.
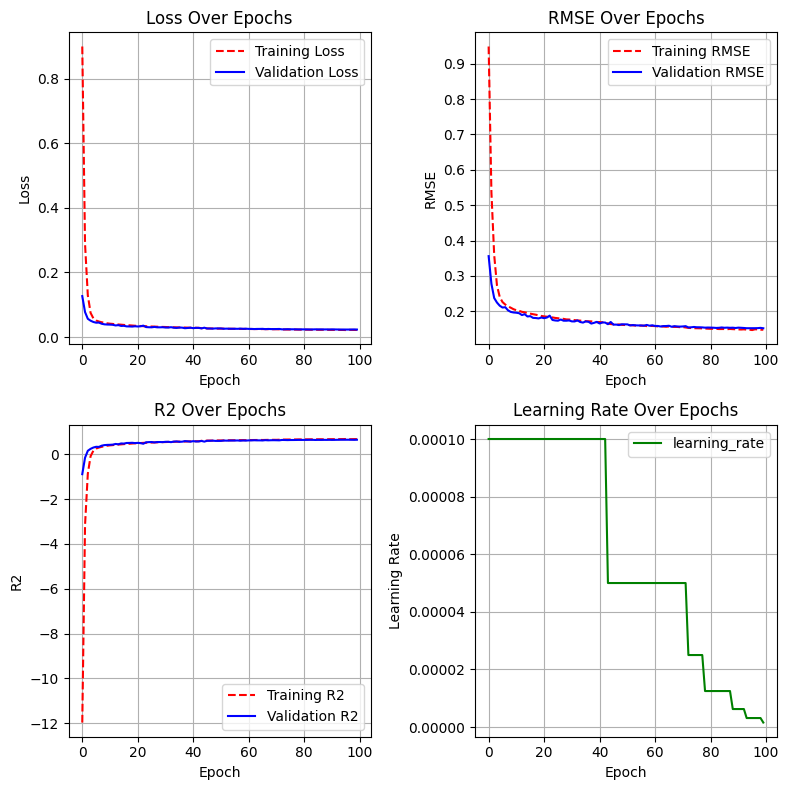
Embeddings Extraction and Model Training: Similar to my previous post, we will extract ESM2 embeddings for both peptides and MHC2 pseudo-sequences. The embeddings will be extracted in a way that retains the 2D structure, which is crucial for applying convolutional layers in the model. After extracting the embeddings, we will concatenate the peptide and MHC2 embeddings along the sequence length dimension, retaining the sequence information and the 2D structure. We will then define a model architecture that includes two 1D convolutional layers followed by a self-attention layer and five dense layers. The model will be trained separately on the datasets generated from the regular C3 split and the strict C3 split, allowing us to compare the performance of the model under both splitting strategies.
Comparing Regular vs. Strict C3 split: After training the model on both datasets, we will evaluate its performance using appropriate metrics such as \(R^2\) score, root mean squared error (RMSE), and loss.
Here we have the peptide sequences, MHC pseudo-sequences, and their corresponding binding affinity values (Y).
Let’s perfrom peptide clustering using a 3-gram approach to find overlapping peptides without source information. We will use the CountVectorizer from sklearn to create a matrix of 3-gram counts for each unique peptide, and then compute the cosine similarity between the peptides based on this matrix. Finally, we will use hierarchical clustering to group similar peptides together.
Code
vect = CountVectorizer(analyzer='char', ngram_range=(3, 3)) # sequence of 3 a.a.pep_matrix = vect.fit_transform(df['Peptide'].unique()) # row: unique peptides, col: unique 3 a.a.pep_sim = cosine_similarity(pep_matrix) # peptide X peptide similarity matrix# use cosine dist when the orientation or pattern of the data is more important than the absolute scale# often used in text, genetic sequence# Cluster peptides that share many 3-mers (likely from the same protein)pep_clusters = AgglomerativeClustering( n_clusters=None, distance_threshold=0.5, # Adjust: lower = more groups, stricter split metric='precomputed', # input is pre-computed dist linkage='complete').fit_predict(1- pep_sim)pep_map = pd.DataFrame({'Peptide': df['Peptide'].unique(),'pep_group': pep_clusters})df = df.merge(pep_map, on='Peptide')
We can see that peptides that are likely from the same protein (e.g., “QYIKANAKFIGITE”, “YATFFIKANSKFIGITE”, “MQYIKANSKFIGITEL”) are clustered together in the same group (group 0). This indicates that our clustering approach is effectively grouping similar peptides together based on their 3-gram composition.
Next, we will cluster MHC pseudo-sequences based on their BLOSUM62 amino acid similarity. We will define a function to calculate the BLOSUM62 similarity between two sequences, and then create a similarity matrix for the MHC pseudo-sequences. Finally, we will use hierarchical clustering to group similar MHCs together.
Code
# Function to calculate BLOSUM62 similaritydef blosum62_similarity(seq1, seq2): matrix = substitution_matrices.load('BLOSUM62') score =0.0# Align sequences by padding the shorter one (simple padding for score calculation)# Note: For rigorous alignment, a proper sequence alignment algorithm (e.g., Needleman-Wunsch) is needed.# This simplified approach assumes aligned positions are comparable.for i inrange(min(len(seq1), len(seq2))):try: score += matrix[seq1[i], seq2[i]]exceptKeyError: # Handle cases where amino acid might not be in BLOSUM (e.g., 'X') score +=0# Normalize score (for simplicity, divide by max possible score)# A more robust normalization might involve the self-similarity score.# Here a max possible similarity score for each aa is calculated and summed max_score1 =sum(matrix[aa, aa] for aa in seq1 if (aa, aa) in matrix.keys()) max_score2 =sum(matrix[aa, aa] for aa in seq2 if (aa, aa) in matrix.keys())if max_score1 ==0or max_score2 ==0: # Avoid division by zeroreturn0.0return score /max(max_score1, max_score2)mhc_sequences = df['MHC'].unique()# Create a similarity matrix for MHCsn_mhc =len(mhc_sequences)mhc_sim_matrix = np.zeros((n_mhc, n_mhc))for i inrange(n_mhc):for j inrange(i, n_mhc): sim = blosum62_similarity(mhc_sequences[i], mhc_sequences[j]) mhc_sim_matrix[i, j] = sim mhc_sim_matrix[j, i] = sim# Cluster MHCsmhc_clusters = AgglomerativeClustering( n_clusters=None, distance_threshold=0.2, # Adjust: lower = more groups, stricter split for MHCs metric='precomputed', linkage='complete').fit_predict(1- mhc_sim_matrix)mhc_map = pd.DataFrame({'MHC': mhc_sequences,'mhc_group': mhc_clusters})df = df.merge(mhc_map, on='MHC')
We can see that MHC pseudo-sequences that are similar based on their BLOSUM62 scores are clustered together in the same group (e.g., “QEFFIASGAAVDAIMELSFEYYVLQKQNYHVVFT”, “QEFFIASGAAVDAIMERSYDYYVLQKRNYHVGFT”, “QEFFIASGAAVDAIMELSFEHYDLQKQNYHVGFT” are all in group 0). This indicates that our clustering approach is effectively grouping similar MHC pseudo-sequences together based on their amino acid composition and similarity.
Next, we will perform the regular C3 split. To ensure total isolation between the training and testing sets, we will create a ‘SuperGroup’ that combines both the peptide and MHC groups. This way, we can ensure that no similar peptide-MHC pairs are present in both the training and testing sets, thus minimizing data leakage.
Code
# Perform the "Regular C3 split" first# We create a 'SuperGroup' that combines both to ensure total isolationdf['super_group'] = df['pep_group'].astype(str) +"_"+ df['mhc_group'].astype(str)# Split train vs temp_testgss = GroupShuffleSplit(n_splits=1, train_size=0.7, random_state=42)train_indices, temp_test_indices =next(gss.split(df, groups=df['super_group']))train_df = df.iloc[train_indices][['Peptide_ID', 'Peptide', 'MHC_ID', 'MHC', 'Y']]temp_test_df = df.iloc[temp_test_indices]# Split temp_text into test and validgss1 = GroupShuffleSplit(n_splits=1, train_size=0.66, random_state=42)test_indices, valid_indices =next(gss1.split(temp_test_df, groups=temp_test_df['super_group']))test_df = df.iloc[test_indices][['Peptide_ID', 'Peptide', 'MHC_ID', 'MHC', 'Y']]valid_df = df.iloc[valid_indices][['Peptide_ID', 'Peptide', 'MHC_ID', 'MHC', 'Y']]
Now, let’s perform the strict C3 split. In this split, we will ensure that for every pair \((Peptide, MHC)\) in the test set, both the peptide and MHC classes are entirely absent from the training set. This means that we will first split the MHC groups and then split the peptide groups independently, ensuring that there is no overlap in either component between the training and testing sets.
Code
def strict_double_split(df, train_size=0.7):# 1. First, split the MHC groups gss_mhc = GroupShuffleSplit(n_splits=1, train_size=train_size, random_state=42) mhc_train_idx, mhc_test_idx =next(gss_mhc.split(df, groups=df['mhc_group'])) mhc_train_alleles = df.iloc[mhc_train_idx]['mhc_group'].unique() mhc_test_alleles = df.iloc[mhc_test_idx]['mhc_group'].unique()# 2. Second, split the Peptides groups# This prevents the model from seeing different fragments of the same protein gss_pep = GroupShuffleSplit(n_splits=1, train_size=train_size, random_state=42) pep_train_idx, pep_test_idx =next(gss_pep.split(df, groups=df['pep_group'])) pep_train_prots = df.iloc[pep_train_idx]['pep_group'].unique() pep_test_prots = df.iloc[pep_test_idx]['pep_group'].unique()# 3. Create the "Strict" Test Set: # Only interactions where BOTH the MHC is new AND the Protein is new. train_df = df[df['mhc_group'].isin(mhc_train_alleles) & df['pep_group'].isin(pep_train_prots)].copy() test_df = df[df['mhc_group'].isin(mhc_test_alleles) & df['pep_group'].isin(pep_test_prots)].copy()return train_df, test_dftrain_temp, test_strict = strict_double_split(df)# Random split of data into train or valid datatrain_strict, valid_strict = train_test_split(train_temp, test_size=0.125, random_state=42)# Save data to discimport ossave_path ='/data'train_df.to_feather(os.path.join(save_path, 'train_dat_cold.feather'))valid_df.to_feather(os.path.join(save_path, 'valid_dat_cold.feather'))test_df.to_feather(os.path.join(save_path, 'test_dat_cold.feather'))train_strict.to_feather(os.path.join(save_path, 'train_dat_strict.feather'))valid_strict.to_feather(os.path.join(save_path, 'valid_dat_strict.feather'))test_strict.to_feather(os.path.join(save_path, 'test_dat_strict.feather'))
We can see that the regular C3 split results in a larger training and testing set compared to the strict C3 split. When we prepare the data for model training, we will need to downsample the regular C3 split to match the sample size of the strict C3 split to ensure a fair comparison between the two splitting strategies.
2. Embeddings Extraction and Model Training
Embedding extraction and model training procedures are similar to my previous post, so I will not go through the code in detail here. Let’s load the data and downsample the regular C3 split to match the sample size of the strict C3 split:
For both data splits, we will extract ESM2 embeddings (facebook/esm2_t30_150M_UR50D) for the peptides and MHC pseudo-sequences, concatenate them, and then train a neural network model with convolutional layers. The model architecture and training procedure will be the same for both splits.
We will now compare the performance of the model trained on the regular C3 split and the strict C3 split using an independent test set. We will evaluate the models using metrics such as \(R^2\) score, root mean squared error (RMSE), and loss.
As we can see, the model trained on the regular C3 split performs significantly better on the test set compared to the model trained on the strict C3 split. The \(R^2\) score is much higher and the RMSE is much lower for the regular C3 split. This suggests that although the model generalizes well on predicting binding peptides of seen MHC2 alleles, it struggles to generalize to unseen MHC2 alleles when using the strict C3 split.
Let’s take a look at the prediction plots:
Regular C3 split prediction plot for all MHC2:
Strict C3 split prediction plot for all MHC2:
Regular C3 split prediction plot separated by MHC2:
Strict C3 split prediction plot separated by MHC2:
As we can see, while the regular C3 split shows good performance across multiple MHC2 alleles, with some achieving an \(R^2\) score > 0.8, the strict C3 split shows max \(R^2\) score of around 0.2 for the best performing MHC2 allele.
Notably, although the total test sample numbers are the same between the two split, due to the strict nature of the strict C3 split, the variety of MHC2 alleles in the test set is much smaller compared to the regular C3 split. Thus, we are perhaps being a little “strict” in our evaluation, since the strict C3 split has not been evaluated on many MHC2 alleles.
This result suggests important limitations for this model: it predicts well on MHC2 alleles that are present in the training data, but it does not perform well on unseen or novel MHC2 alleles. Perhaps the model is very good at memorizing specific interactions between peptides and MHC2 alleles, but did not learn well the general rules of protein-protein interaction, which is also a significant challenge for many PPI prediction models utilizing pLLMs. Some potential solutions to this issue could include:
Increasing the diversity of the training data to include a wider range of MHC2 alleles, which may help the model learn more generalizable patterns.
Incorporating additional features or using more complex model architectures that can capture the underlying biology of peptide binding to MHC2 molecules, rather than relying solely on the embeddings from the pre-trained pLLM.
Re-train a pLLM on strict data with held out samples, so that the embeddings themselves are less prone to data leakage and more generalizable to unseen data.
Conclusion
In this project, I explored the issue of data leakage in peptide-MHC2 binding prediction models using pre-trained protein language models (pLLMs). I compared two data splitting strategies, a regular C3 split and a strict C3 split, to evaluate the extent of data leakage and its impact on model performance. My findings showed that while the model trained on the regular C3 split performed well on the test set, it struggled to generalize to unseen MHC2 alleles when evaluated using the strict C3 split. This highlights the importance of using stringent data splitting strategies to ensure that models are evaluated on truly unseen data, which is crucial for developing robust and generalizable models in protein binding affinity prediction.